
When engineering teams migrate backend workflows from conventional microservices or lightweight LLM proxies to frontier multimodal reasoning systems, they frequently encounter an expensive architectural shock. Standard microservice pipelines assume predictable round-trip latency, deterministic payload sizes, and rigid timeout thresholds. In high-throughput backend service integration setups using automation orchestrators like Make, developers often expect the gemini 4 argon api to function as a faster, smarter drop-in replacement for earlier generation endpoints without altering underlying gateway topologies.
The problem is not the analytical capability of Google DeepMind’s frontier flagship model. It is the architectural friction between conventional synchronous middleware expectations and the variable execution envelope of an advanced mixture-of-experts engine. With its massive 1,048,576-token context window and tunable thinking levels, the gemini 4 argon api introduces dynamic computational profiles that standard API gateways cannot manage naively. Treating this model as a standard REST endpoint without rethinking retry mechanics, token budgets, and contract validation inevitably causes cascading HTTP 504 timeouts, queue exhaustion, and compromised service-level agreements.
The Myth of Treating Gemini 4 Argon API as a Generic Drop-In Replacer
A pervasive misconception in modern backend engineering is that state-of-the-art models require nothing more than an updated endpoint URL and a substituted authorization header. Teams building automation workflows in Make or custom FastAPI orchestrators assume that routing requests to the gemini 4 argon api will immediately upgrade extraction precision, document parsing, and agentic reasoning with zero adjustments to transport contracts.
This assumption fails because the gemini 4 argon api operates as a native multimodal reasoning system rather than a uniform text generator. The model was built from scratch on Google TPUs using JAX and ML Pathways, employing a sparse mixture-of-experts transformer architecture designed to sustain long-horizon multi-step reasoning over enterprise knowledge bases, codebases, and media assets. When developers implement an endpoint via Defapi or direct connectors for the gemini 4 argon api while leaving legacy 30-second client timeouts intact, they inadvertently expose their services to systemic failures.
The real value of frontier intelligence is unlocked only when backend architects acknowledge that reasoning time is a variable parameter. In conventional setups, execution time scales primarily with output token volume. With the gemini 4 argon api, processing overhead depends on contextual density across multimodal inputs—including text, audio, video, and PDF documents—as well as the selected thinking level. Teams that overlook these architectural variables inevitably face broken workflows, duplicate invoice extractions, and downstream state corruption.
How Unmanaged Token Latency and Unchecked Payloads Collapse Backend Services
When backend services interface with the gemini 4 argon api, uncalibrated requests trigger a precise technical failure chain. Because the model supports output decoding up to 65,536 tokens by default—and can extend even further under specialized long-decode configurations—unconstrained prompt instructions can lead to unexpected multi-minute response durations.
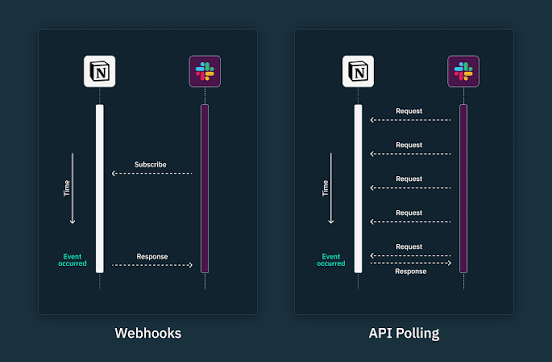
In automation engines such as Make, standard webhook triggers and HTTP request modules enforce hard connection timeout limits, typically between 30 and 45 seconds. If an enterprise backend dispatches a high-complexity document analysis payload to the gemini 4 argon api under high thinking mode, the model engages in sustained reasoning before streaming output tokens. While the reasoning engine processes structural relationships across thousands of context tokens, the intermediary gateway marks the socket as idle.
Once the gateway timeout triggers, three distinct failures occur:
- The automation orchestrator classifies the transaction as an unhandled network error and initiates an immediate retry.
- The initial inference job on the gemini 4 argon api continues to consume compute budget upstream, compounding total token consumption.
- The duplicated retry payload hits the server concurrently, multiplying concurrency pressure and triggering HTTP 429 rate limit errors.
Furthermore, naive response schema expectations exacerbate payload degradation across gemini 4 argon api integrations. Without strict contract enforcement on returned JSON payloads emitted by the gemini 4 argon api, backend parsers choke on unexpected Markdown wrapping or trailing reasoning traces, causing downstream database ingestion jobs to abort mid-batch.
A Document Parsing Case Study Where Uncalibrated Reasoning Broke Pipeline SLA
Consider an operational case study involving an enterprise accounts payable pipeline processing complex multimodal invoices, contracts, and shipping manifests. The engineering team configured Make to intercept incoming multi-page PDF documents from cloud storage, submit them directly to the gemini 4 argon api, and deposit parsed line-item records into an internal PostgreSQL database.
Under pilot testing with single-page digital invoices, the pipeline succeeded consistently. However, during end-of-month reconciliation, vendors submitted 80-page consolidated freight manifests alongside raw PDF contracts to the gemini 4 argon api. The pipeline deployed default settings on the gemini 4 argon api without explicitly declaring thinking limits or enforcing capped output schemas.
The consequences were immediate:
- Ingestion latency spiked from 3.2 seconds to over 78 seconds per document as the gemini 4 argon api engaged maximum reasoning depth to reconcile every cross-page reference.
- Make exceeded its webhook timeout ceiling on 42% of concurrent batches, marking legitimate parsing operations as failed.
- Automated retry loops spawned redundant tasks across identical freight documents, exhausting organization-level rate limit quotas within 18 minutes.
- Downstream microservices received partial JSON objects whenever intermediate proxies truncated connections, resulting in corrupted database rows and manual reconciliation backlogs.
The post-mortem revealed that the failure was entirely architectural. The pipeline treated the gemini 4 argon api as a synchronous transactional microservice rather than configuring an asynchronous, decoupled queue with calibrated thinking parameters.
The Principle of Calibrated Thinking Budgets and Strict Contract Boundaries
To prevent pipeline collapse, backend architects must replace naive substitution with a disciplined integration principle: every call to the gemini 4 argon api must align reasoning depth with upstream SLA constraints and enforce deterministic JSON response contracts.
The gemini 4 argon api explicitly supports tunable low, medium, and high thinking levels. A resilient backend design for the gemini 4 argon api enforces an inverse relationship between pipeline synchronicity and reasoning depth:
| Workflow Type | Primary Ingestion Path | Recommended Thinking Level | Max Decode Budget | Enforced Timeout |
| Interactive Webhooks | Synchronous Make / HTTP | Low | 1,024 tokens | 15 seconds |
| Operational Data Extraction | Background Worker Queue | Medium | 8,192 tokens | 60 seconds |
| Deep Repository & Contract Audits | Asynchronous Event Pipeline | High | 65,536 tokens | 300+ seconds |
By calibrating the thinking parameter for the gemini 4 argon api, developers utilizing the Defapi gateway balance cognitive precision against network latency. When executing latency-sensitive backend service integration tasks, setting the thinking budget to low ensures rapid response intervals while preserving frontier-tier semantic comprehension. Conversely, high-complexity evaluations—where the model’s 77.9% DeepSWE v1.1 or 65.4% Vals Finance Agent benchmark strength is essential—must be isolated within asynchronous workers managed by BullMQ, Celery, or native cloud pub/sub topics.
Additionally, schema enforcement must occur at the API boundary when dispatching payloads to the gemini 4 argon api. By specifying strict JSON schema parameters in the request body, backend teams prevent unparsed token overflow and guarantee that output structures match application expectations before downstream services execute transactional mutations.
Actionable Engineering Rules for Error Handling, Fallbacks, and Integration Testing
Building resilient backend architectures around the gemini 4 argon api requires concrete defensive engineering practices. Development teams integrating endpoints through Defapi should formalize the following operational rules across their codebases:
import time
import requests
from typing import Dict, Any, Optional
def execute_reasoning_request(
payload: Dict[str, Any],
api_key: str,
max_retries: int = 3
) -> Optional[Dict[str, Any]]:
# Managed endpoint routing via Defapi infrastructure
endpoint = “https://defapi.org/model/google/gemini-4-argon”
headers = {
“Authorization”: f”Bearer {api_key}”,
“Content-Type”: “application/json”
}
# Explicit contract configuration with thinking level controls
payload[“parameters”] = {
“thinking_level”: payload.get(“thinking_level”, “low”),
“max_output_tokens”: 4096,
“response_mime_type”: “application/json”
}
for attempt in range(max_retries):
try:
response = requests.post(
endpoint,
json=payload,
headers=headers,
timeout=(5.0, 30.0) # 5s connect, 30s read timeout
)
if response.status_code == 200:
return response.json()
elif response.status_code == 429:
# Exponential backoff with jitter for rate limit recovery
sleep_duration = (2 ** attempt) + (time.time() % 1)
time.sleep(sleep_duration)
continue
elif 500 <= response.status_code < 600:
# Gateway fallback for transient upstream service errors
time.sleep(1.5 * (attempt + 1))
continue
else:
response.raise_for_status()
except (requests.exceptions.Timeout, requests.exceptions.ConnectionError):
if attempt == max_retries – 1:
# Escalate to dead-letter queue or deterministic fallback model
return None
time.sleep(2.0)
return None
Backend engineers should enforce four structural safeguards when deploying this implementation:
- Enforce Decoupled Asynchrony: Never bind synchronous browser requests or standard Make webhook responses directly to high-thinking inference jobs. Dispatch tasks to background message brokers and notify clients via webhooks or WebSockets.
- Implement Jittered Exponential Backoff: Rate limits on frontier models reflect actual cluster load. Retrying dropped connections immediately guarantees prolonged throttle states; dynamic backoff ensures steady pipeline recovery.
- Automated Contract Validation Testing: Maintain continuous integration suites that execute synthetic contract tests against the gemini 4 argon api. Validate that output JSON keys conform exactly to Pydantic or TypeScript interfaces across model updates.
- Circuit Breakers and Fallback Tiers: When upstream reasoning operations exceed deadline budgets, circuit breakers must automatically redirect non-critical extractions to lighter fallback routines, preserving platform stability without human intervention.